


2025 Latest 100% Exam Passing Ratio - MuleSoft-Platform-Architect-I Dumps PDF
Pass Exam With Full Sureness - MuleSoft-Platform-Architect-I Dumps with 154 Questions
Salesforce MuleSoft-Platform-Architect-I Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
| Topic 6 |
|
| Topic 7 |
|
| Topic 8 |
|
NEW QUESTION # 27
An API is protected with a Client ID Enforcement policy and uses the default configuration. Access is requested for the client application to the API, and an approved contract now exists between the client application and the API How can a consumer of this API avoid a 401 error "Unauthorized or invalid client application credentials"?
- A. Send the obtained: client_id and client_secret in the request body
- B. Send the obtained token as a header in every call
- C. Send the obtained clent_id and clent_secret as URI parameters in every call
- D. Send the obtained clent_id and client_secret in the header of every API Request call
Answer: C
Explanation:
When using the Client ID Enforcement policy with default settings, MuleSoft expects the client_id and client_secret to be provided in the URI parameters of each request. This policy is typically used to control and monitor access by validating that each request has valid credentials. Here's how to avoid a 401 Unauthorized error:
URI Parameters Requirement:
The default configuration for the Client ID Enforcement policy requires the client_id and client_secret to be included in each request's URI parameters. This is a straightforward way to authenticate API requests without additional configurations.
Why Option C is Correct:
Providing client_id and client_secret in the URI parameters meets the policy's requirements for each request, ensuring authorized access and avoiding the 401 error.
of Incorrect Options:
Option A (sending a token in the header) would be applicable for token-based authentication (like OAuth 2.0), not Client ID Enforcement.
Option B (request body) and Option D (header) are not valid locations for client_id and client_secret under the default configuration of Client ID Enforcement, which expects them in the URI.
Reference
For more details, consult MuleSoft's documentation on Client ID Enforcement policies and expected request configurations
NEW QUESTION # 28
Once an API Implementation is ready and the API is registered on API Manager, who should request the access to the API on Anypoint Exchange?
- A. Both
- B. API Consumer
- C. API Client
- D. None
Answer: B
Explanation:
Correct Answer : API Consumer
*****************************************
>> API clients are piece of code or programs that use the client credentials of API consumer but does not directly interact with Anypoint Exchange to get the access
>> API consumer is the one who should get registered and request access to API and then API client needs to use those client credentials to hit the APIs So, API consumer is the one who needs to request access on the API from Anypoint Exchange
NEW QUESTION # 29
What do the API invocation metrics provided by Anypoint Platform provide?
- A. Measurements of the effectiveness of the application network based on the level of reuse
- B. Proactive identification of likely future policy violations that exceed a given threat threshold
- C. Data on past API invocations to help identify anomalies and usage patterns across various APIs
- D. ROI metrics from APIs that can be directly shared with business users
Answer: C
Explanation:
Correct Answer : Data on past API invocations to help identify anomalies and usage patterns across various APIs
*****************************************
API Invocation metrics provided by Anypoint Platform:
>> Does NOT provide any Return Of Investment (ROI) related information. So the option suggesting it is OUT.
>> Does NOT provide any information w.r.t how APIs are reused, whether there is effective usage of APIs or not etc...
>> Does NOT prodive any prediction information as such to help us proactively identify any future policy violations.
So, the kind of data/information we can get from such metrics is on past API invocations to help identify anomalies and usage patterns across various APIs.
NEW QUESTION # 30
A European company has customers all across Europe, and the IT department is migrating from an older platform to MuleSoft. The main requirements are that the new platform should allow redeployments with zero downtime and deployment of applications to multiple runtime versions, provide security and speed, and utilize Anypoint MQ as the message service.
Which runtime plane should the company select based on the requirements without additional network configuration?
- A. Customer-hosted runtime plane
- B. Runtime Fabric on VMs / Bare Metal for the runtime plane
- C. Anypoint Runtime Fabric on Self-Managed Kubernetes for the runtime plane
- D. MuleSoft-hosted runtime plane (CloudHub)
Answer: D
Explanation:
For a European company with requirements such as zero-downtime redeployment, deployment to multiple runtime versions, secure and fast performance, and the use of Anypoint MQ without additional network configuration, CloudHub is the best choice for the following reasons:
Zero-Downtime Redeployment: CloudHub supports zero-downtime deployment, which allows seamless redeployment of applications without impacting availability.
Support for Multiple Runtime Versions: CloudHub allows deploying applications across different Mule runtime versions, giving flexibility to test and migrate applications as needed.
Integrated Anypoint MQ: Anypoint MQ, which is fully integrated with CloudHub, provides reliable messaging across applications. Choosing CloudHub removes the need for additional network configurations, as Anypoint MQ can be directly accessed in this hosted environment.
Security and Performance: CloudHub offers secure networking, automatic scaling, and optimized performance without requiring a complex setup. This is managed by MuleSoft's infrastructure, meeting the speed and security requirements with minimal overhead.
of Incorrect Options:
Option A and D (Runtime Fabric on VMs or Self-Managed Kubernetes): While Runtime Fabric offers flexibility, it requires more complex network and infrastructure configurations, which is not ideal if the company seeks simplicity.
Option B (Customer-hosted): This would require additional network and security configuration, which does not align with the requirement of minimizing setup complexity.
Reference
For more information on CloudHub's capabilities regarding zero-downtime deployments and integration with Anypoint MQ, refer to MuleSoft documentation on CloudHub.
NEW QUESTION # 31
Refer to the exhibit.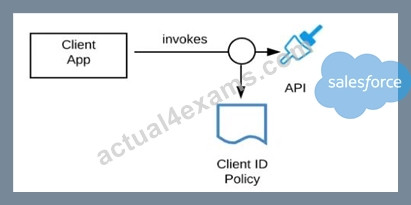
A developer is building a client application to invoke an API deployed to the STAGING environment that is governed by a client ID enforcement policy.
What is required to successfully invoke the API?
- A. The client ID and secret obtained from Anypoint Exchange for the API instance in the STAGING environment
- B. A valid OAuth token obtained from Anypoint Platform and its associated client ID and secret
- C. The client ID and secret for the Anypoint Platform account owning the API in the STAGING environment
- D. The client ID and secret for the Anypoint Platform account's STAGING environment
Answer: A
Explanation:
Correct Answer : The client ID and secret obtained from Anypoint Exchange for the API instance in the STAGING environment
*****************************************
>> We CANNOT use the client ID and secret of Anypoint Platform account or any individual environments for accessing the APIs
>> As the type of policy that is enforced on the API in question is "Client ID Enforcment Policy", OAuth token based access won't work.
Right way to access the API is to use the client ID and secret obtained from Anypoint Exchange for the API instance in a particular environment we want to work on.
Reference:
Managing API instance Contracts on API Manager
https://docs.mulesoft.com/api-manager/1.x/request-access-to-api-task
https://docs.mulesoft.com/exchange/to-request-access
https://docs.mulesoft.com/api-manager/2.x/policy-mule3-client-id-based-policies
NEW QUESTION # 32
What condition requires using a CloudHub Dedicated Load Balancer?
- A. When API invocations across multiple CloudHub workers must be load balanced
- B. When cross-region load balancing is required between separate deployments of the same Mule application
- C. When server-side load-balanced TLS mutual authentication is required between API implementations and API clients
- D. When custom DNS names are required for API implementations deployed to customer-hosted Mule runtimes
Answer: C
Explanation:
Correct Answer : When server-side load-balanced TLS mutual authentication is required between API implementations and API clients
*****************************************
Fact/ Memory Tip: Although there are many benefits of CloudHub Dedicated Load balancer, TWO important things that should come to ones mind for considering it are:
>> Having URL endpoints with Custom DNS names on CloudHub deployed apps
>> Configuring custom certificates for both HTTPS and Two-way (Mutual) authentication.
Coming to the options provided for this question :
>> We
CANNOT use DLB to perform cross-region load balancing between separate deployments of the same Mule application.
>> We can have mapping rules to have more than one DLB URL pointing to same Mule app. But vicevera (More than one Mule app having same DLB URL) is NOT POSSIBLE
>> It is true that DLB helps to setup custom DNS names for Cloudhub deployed Mule apps but NOT true for apps deployed to Customer-hosted Mule Runtimes.
>> It is true to that we can load balance API invocations across multiple CloudHub workers using DLB but it is NOT A MUST. We can achieve the same (load balancing) using SLB (Shared Load Balancer) too. We DO NOT necessarily require DLB for achieve it.
So the only right option that fits the scenario and requires us to use DLB is when TLS mutual authentication is required between API implementations and API clients.
NEW QUESTION # 33
A company stores financial transaction data in two legacy systems. For each legacy system, a separate, dedicated System API (SAPI) exposes data for that legacy system. A Process API (PAPI) merges the data retrieved from ail of the System APIs into a common format. Several API clients call the PAPI through its public domain name.
The company now wants to expose a subset of financial data to a newly developed mobile application that uses a different Bounded Context Data Model. The company wants to follow MuleSoft's best practices for building out an effective application network.
Following MuleSoft's best practices, how can the company expose financial data needed by the mobile application in a way that minimizes the impact on the currently running API clients, API implementations, and support asset reuse?
- A. Add two new Experience APIs (EAPI-i and EAPI-2}.
Add Mobile PAPI-2 to expose the Intended subset of financial data as requested.
Both PAPIs access the Legacy Systems via SAPI-1 and SAP]-2. - B. Develop and deploy is new PAPI implementation with data transformation and ... login to support this required endpoints of both mobile and web clients.
Deploy an API Proxy with an endpoint from API Manager that redirect the existing PAPI endpoints to the new PAPI. - C. Create a new mobile Experince API (EAPI) chat exposes that subset of PAPI endpoints.
Add transformtion login to the mobile Experince API implementation to make mobile data compatible with the required PAPIs.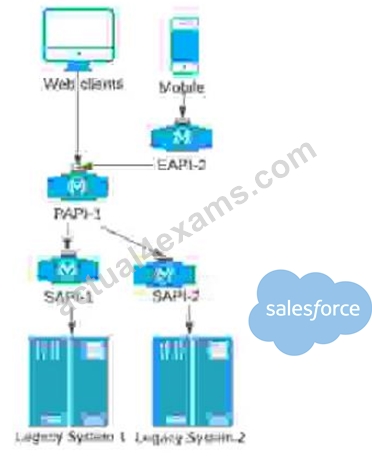
- D. Add two new Experience APIs (EAPI-i and EAPI-2}.
Add Mobile PAPI-2 to expose the Intended subset of financial data as requested.
Both PAPIs access the Legacy Systems via SAPI-1 and SAP]-2.
Answer: D
Explanation:
To achieve the goal of exposing financial data to a new mobile application while following MuleSoft's best practices, the company should follow an API-led connectivity approach. This approach ensures minimal disruption to existing clients, maximizes reusability, and respects the separation of concerns across API layers.
of Solution:
Experience APIs for Client-Specific Requirements:
Create two new Experience APIs (EAPI-1 and EAPI-2) for the mobile application, tailored to meet the specific data and format requirements of the mobile application. These APIs encapsulate the client-specific needs and provide a custom interface without impacting other clients.
Process API Layer for Data Transformation:
By adding Mobile PAPI-2, we allow the mobile application to access the required subset of data, formatted according to the mobile application's requirements. This approach ensures that data transformation and aggregation are handled in the Process layer, maintaining consistency and reusability across different applications.
Reuse of System APIs:
Both the new Mobile PAPI-2 and existing PAPI-1 access data from System APIs (SAPI-1 and SAPI-2), which continue to expose data from each legacy system in a consistent, reusable manner. This avoids duplicating logic and ensures that data access remains centralized and manageable.
Why Option A is Correct:
Option A aligns with MuleSoft's best practices by isolating client-specific requirements in the Experience layer, utilizing Process APIs for data orchestration and transformation, and maintaining reusable System APIs for backend access.
This approach also ensures that the current API clients are not impacted, as new clients (e.g., the mobile app) interact with newly defined Experience APIs without modifying the existing API setup.
of Incorrect Options:
Option B: This option seems similar but lacks clarity on the separation of mobile-specific requirements and does not explicitly mention data transformation, which is essential in this scenario.
Option C: Creating a single mobile Experience API that exposes a subset of PAPI endpoints directly adds unnecessary complexity and may violate the separation of concerns, as transformation logic should not be in the Experience layer.
Option D: Deploying a new PAPI and using an API Proxy to redirect existing endpoints would add unnecessary complexity, disrupt the current API clients, and increase maintenance efforts.
Reference
For additional guidance, refer to MuleSoft documentation on API-led connectivity best practices and best practices for structuring Experience, Process, and System APIs.
NEW QUESTION # 34
What best explains the use of auto-discovery in API implementations?
- A. It enables Anypoint Analytics to gain insight into the usage of APIs
- B. It makes API Manager aware of API implementations and hence enables it to enforce policies
- C. It enables Anypoint Studio to discover API definitions configured in Anypoint Platform
- D. It enables Anypoint Exchange to discover assets and makes them available for reuse
Answer: B
Explanation:
Correct Answer : It makes API Manager aware of API implementations and hence enables it to enforce policies.
*****************************************
>> API Autodiscovery is a mechanism that manages an API from API Manager by pairing the deployed application to an API created on the platform.
>> API Management includes tracking, enforcing policies if you apply any, and reporting API analytics.
>> Critical to the Autodiscovery process is identifying the API by providing the API name and version.
Reference:
https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept
https://docs.mulesoft.com/api-manager/1.x/api-auto-discovery
https://docs.mulesoft.com/api-manager/2.x/api-auto-discovery-new-concept
NEW QUESTION # 35
When designing an upstream API and its implementation, the development team has been advised to NOT set timeouts when invoking a downstream API, because that downstream API has no SLA that can be relied upon. This is the only downstream API dependency of that upstream API.
Assume the downstream API runs uninterrupted without crashing. What is the impact of this advice?
- A. A default timeout of 500 ms will automatically be applied by the Mule runtime in which the upstream API implementation executes
- B. An SLA for the upstream API CANNOT be provided
- C. A toad-dependent timeout of less than 1000 ms will be applied by the Mule runtime in which the downstream API implementation executes
- D. The invocation of the downstream API will run to completion without timing out
Answer: B
Explanation:
Correct Answer : An SLA for the upstream API CANNOT be provided.
*****************************************
>> First thing first, the default HTTP response timeout for HTTP connector is 10000 ms (10 seconds). NOT 500 ms.
>> Mule runtime does NOT apply any such "load-dependent" timeouts. There is no such behavior currently in Mule.
>> As there is default 10000 ms time out for HTTP connector, we CANNOT always guarantee that the invocation of the downstream API will run to completion without timing out due to its unreliable SLA times. If the response time crosses 10 seconds then the request may time out.
The main impact due to this is that a proper SLA for the upstream API CANNOT be provided.
NEW QUESTION # 36
What is a key requirement when using an external Identity Provider for Client Management in Anypoint Platform?
- A. APIs managed by Anypoint Platform must be protected by SAML 2.0 policies
- B. The application network must include System APIs that interact with the Identity Provider
- C. Single sign-on is required to sign in to Anypoint Platform
- D. To invoke OAuth 2.0-protected APIs managed by Anypoint Platform, API clients must submit access tokens issued by that same Identity Provider
Answer: D
Explanation:
https://www.folkstalk.com/2019/11/mulesoft-integration-and-platform.html Correct Answer : To invoke OAuth 2.0-protected APIs managed by Anypoint Platform, API clients must submit access tokens issued by that same Identity Provider
*****************************************
>> It is NOT necessary that single sign-on is required to sign in to Anypoint Platform because we are using an external Identity Provider for Client Management
>> It is NOT necessary that all APIs managed by Anypoint Platform must be protected by SAML 2.0 policies because we are using an external Identity Provider for Client Management
>> Not TRUE that the application network must include System APIs that interact with the Identity Provider because we are using an external Identity Provider for Client Management Only TRUE statement in the given options is - "To invoke OAuth 2.0-protected APIs managed by Anypoint Platform, API clients must submit access tokens issued by that same Identity Provider" Reference:
https://docs.mulesoft.com/api-manager/2.x/external-oauth-2.0-token-validation-policy
https://blogs.mulesoft.com/dev/api-dev/api-security-ways-to-authenticate-and-authorize/
NEW QUESTION # 37
Question 10: Skipped
An API implementation returns three X-RateLimit-* HTTP response headers to a requesting API client. What type of information do these response headers indicate to the API client?
- A. The remaining capacity allowed by the API implementation
- B. The HTTP response size
- C. The error codes that result from throttling
- D. A correlation ID that should be sent in the next request
Answer: A
Explanation:
Correct Answe r: The remaining capacity allowed by the API implementation.
*****************************************
>> Reference: https://docs.mulesoft.com/api-manager/2.x/rate-limiting-and-throttling-sla-based-policies#response-headers
NEW QUESTION # 38
How are an API implementation, API client, and API consumer combined to invoke and process an API?
- A. The ApI client creates an API consumer, which sends API invocations to an API such that they are processed by an API implementation
- B. The ApI consumer creates an API client, which sends API invocations to an API such that they are processed by an API implementation
- C. The API client creates an API consumer, which receives API invocations from an API such that they are processed for an API implementation
- D. The API consumer creates an API implementation, which receives API invocations from an API such that they are processed for an API client
Answer: B
Explanation:
Correct Answer : The API consumer creates an API client, which sends API invocations to an API such that they are processed by an API implementation
*****************************************
Terminology:
>> API Client - It is a piece of code or program the is written to invoke an API
>> API Consumer - An owner/entity who owns the API Client. API Consumers write API clients.
>> API - The provider of the API functionality. Typically an API Instance on API Manager where they are managed and operated.
>> API Implementation - The actual piece of code written by API provider where the functionality of the API is implemented. Typically, these are Mule Applications running on Runtime Manager.
NEW QUESTION # 39
Refer to the exhibit.
Three business processes need to be implemented, and the implementations need to communicate with several different SaaS applications.
These processes are owned by separate (siloed) LOBs and are mainly independent of each other, but do share a few business entities. Each LOB has one development team and their own budget In this organizational context, what is the most effective approach to choose the API data models for the APIs that will implement these business processes with minimal redundancy of the data models?
A) Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities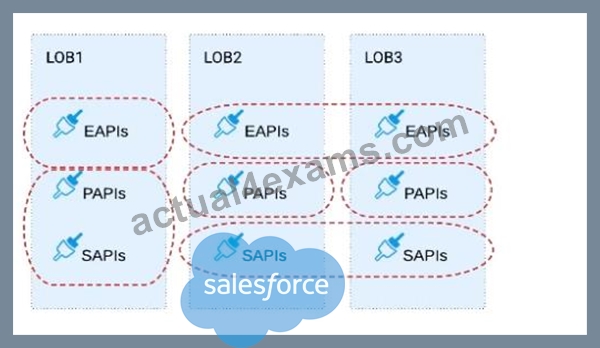
B) Build distinct data models for each API to follow established micro-services and Agile API-centric practices C) Build all API data models using XML schema to drive consistency and reuse across the organization D) Build one centralized Canonical Data Model (Enterprise Data Model) that unifies all the data types from all three business processes, ensuring the data model is consistent and non-redundant
- A. Option D
- B. Option B
- C. Option A
- D. Option C
Answer: C
Explanation:
Correct Answe r: Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.
*****************************************
>> The options w.r.t building API data models using XML schema/ Agile API-centric practices are irrelevant to the scenario given in the question. So these two are INVALID.
>> Building EDM (Enterprise Data Model) is not feasible or right fit for this scenario as the teams and LOBs work in silo and they all have different initiatives, budget etc.. Building EDM needs intensive coordination among all the team which evidently seems not possible in this scenario.
So, the right fit for this scenario is to build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.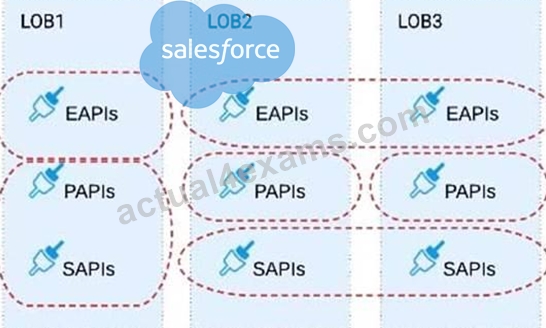
NEW QUESTION # 40
What CANNOT be effectively enforced using an API policy in Anypoint Platform?
- A. Logging HTTP requests and responses
- B. Maintaining tamper-proof credentials between APIs
- C. Guarding against Denial of Service attacks
- D. Backend system overloading
Answer: C
Explanation:
Correct Answer : Guarding against Denial of Service attacks
*****************************************
>> Backend system overloading can be handled by enforcing "Spike Control Policy"
>> Logging HTTP requests and responses can be done by enforcing "Message Logging Policy"
>> Credentials can be tamper-proofed using "Security" and "Compliance" Policies However, unfortunately, there is no proper way currently on Anypoint Platform to guard against DOS attacks.
NEW QUESTION # 41
What Anypoint Platform Capabilities listed below fall under APIs and API Invocations/Consumers category? Select TWO.
- A. API Consumer Engagement
- B. API Design and Development
- C. API Operations and Management
- D. API Runtime Execution and Hosting
Answer: B
Explanation:
Correct Answers: API Design and Development and API Runtime Execution and Hosting
*****************************************
>> API Design and Development - Anypoint Studio, Anypoint Design Center, Anypoint Connectors
>> API Runtime Execution and Hosting - Mule Runtimes, CloudHub, Runtime Services
>> API Operations and Management - Anypoint API Manager, Anypoint Exchange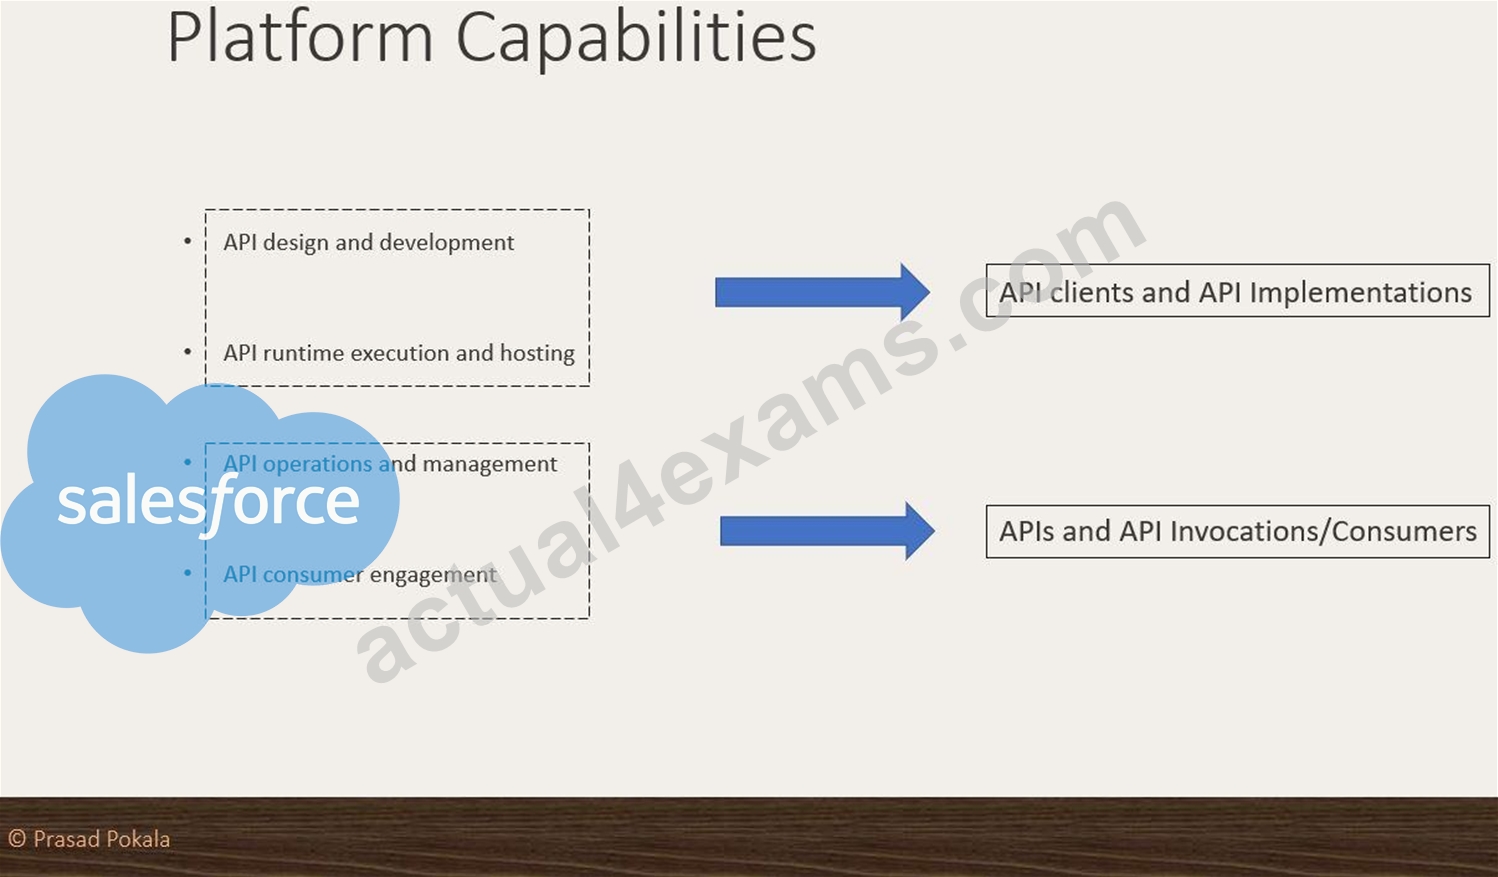
Correct Answers: API Operations and Management and API Consumer Engagement
*****************************************
>> API Design and Development - Anypoint Studio, Anypoint Design Center, Anypoint Connectors
>> API Runtime Execution and Hosting - Mule Runtimes, CloudHub, Runtime Services
>> API Operations and Management - Anypoint API Manager, Anypoint Exchange
>> API Consumer Management - API Contracts, Public Portals, Anypoint Exchange, API Notebooks
Bottom of Form
Top of Form
NEW QUESTION # 42
An API implementation is deployed to CloudHub.
What conditions can be alerted on using the default Anypoint Platform functionality, where the alert conditions depend on the API invocations to an API implementation?
- A. When the API invocations are sent directly to the internal DNS record of the API implementation
- B. When the API invocations are not over-a- secure TLS/SSL communication channel
- C. When the APL invecations originate from a geography different than the API
- D. When the number of API invocations are below a threshold
Answer: D
Explanation:
Default Alert Capabilities in Anypoint Platform:
Anypoint Platform provides out-of-the-box alerting capabilities for monitoring API invocation conditions, including setting thresholds for the number of invocations.
Alerts can be configured for conditions such as high or low traffic (invocations exceeding or falling below a defined threshold).
Evaluating the Options:
Option A: Anypoint Platform does not provide direct alerting based on DNS records.
Option B: Anypoint Platform does not provide default alerts based on whether invocations use TLS/SSL; this would require custom configuration.
Option C: Geolocation-based alerting is not natively supported in Anypoint Platform.
Option D (Correct Answer): Alerts based on API invocation thresholds (e.g., invocations falling below a set threshold) are supported and can be configured as part of the default Anypoint alerting functionality.
Conclusion:
Option D is correct, as Anypoint Platform allows configuring alerts based on the number of API invocations falling below or exceeding a threshold.
Refer to MuleSoft's documentation on Anypoint Monitoring and alert configurations for more details.
NEW QUESTION # 43
What Mule application deployment scenario requires using Anypoint Platform Private Cloud Edition or Anypoint Platform for Pivotal Cloud Foundry?
- A. When it Is required to make ALL applications highly available across multiple data centers
- B. When it is required that ALL APIs are private and NOT exposed to the public cloud
- C. When ALL backend systems in the application network are deployed in the organization's intranet
- D. When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data
Answer: D
Explanation:
Correct Answer : When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data.
*****************************************
We need NOT require to use Anypoint Platform PCE or PCF for the below. So these options are OUT.
>> We can make ALL applications highly available across multiple data centers using CloudHub too.
>> We can use Anypoint VPN and tunneling from CloudHub to connect to ALL backend systems in the application network that are deployed in the organization's intranet.
>> We can use Anypoint VPC and Firewall Rules to make ALL APIs private and NOT exposed to the public cloud.
Only valid reason in the given options that requires to use Anypoint Platform PCE/ PCF is - When regulatory requirements mandate on-premises processing of EVERY data item, including meta-data.
NEW QUESTION # 44
An enterprise is embarking on the API-led digital transformation journey, and the central IT team has started to define System APIs. Currently there is no Enterprise Data Model being defined within the enterprise, and the definition of a clean Bounded Context Data Model requires too much effort.
According to MuleSoft's recommended guidelines, how should the System API data model be defined?
- A. The data model should define its own naming convention, and not follow the same naming as the back-end systems
- B. The System APIs should expose all back-end system fields
- C. The data model of the System APIs should make use of data types that approximately mirror those from the back-end systems
- D. If there are misspellings of the data fields in the back-end system, Systerm APIs should not correct it, and expose it as-is to mirror the back-end systems
Answer: C
Explanation:
When defining data models for System APIs without an established Enterprise Data Model, MuleSoft recommends mirroring the back-end systems' data types to achieve quick and effective integration without adding complexity. This approach has several benefits:
Alignment with Backend Systems:
Mirroring data types ensures consistency with backend data sources, which simplifies integration, reduces mapping requirements, and minimizes potential data transformation issues.
Flexibility for Future Enhancements:
By retaining close alignment with backend data structures, System APIs can evolve to support an Enterprise Data Model in the future without immediate restructuring.
of Incorrect Options:
Option A (exposing misspellings) is not recommended as System APIs should still ensure a professional and coherent interface.
Option C (custom naming) complicates the API structure without adding immediate value in the absence of a clear data model.
Option D (exposing all fields) is unnecessary and can reduce performance and add complexity.
Reference
Refer to MuleSoft best practices for data modeling in System APIs for additional information on mirroring backend systems.
NEW QUESTION # 45
Question 10: Skipped
An API implementation returns three X-RateLimit-* HTTP response headers to a requesting API client. What type of information do these response headers indicate to the API client?
- A. The remaining capacity allowed by the API implementation
- B. The HTTP response size
- C. The error codes that result from throttling
- D. A correlation ID that should be sent in the next request
Answer: A
Explanation:
Correct Answer : The remaining capacity allowed by the API implementation.
*****************************************
>> Reference: https://docs.mulesoft.com/api-manager/2.x/rate-limiting-and-throttling-sla-based-policies#response-headers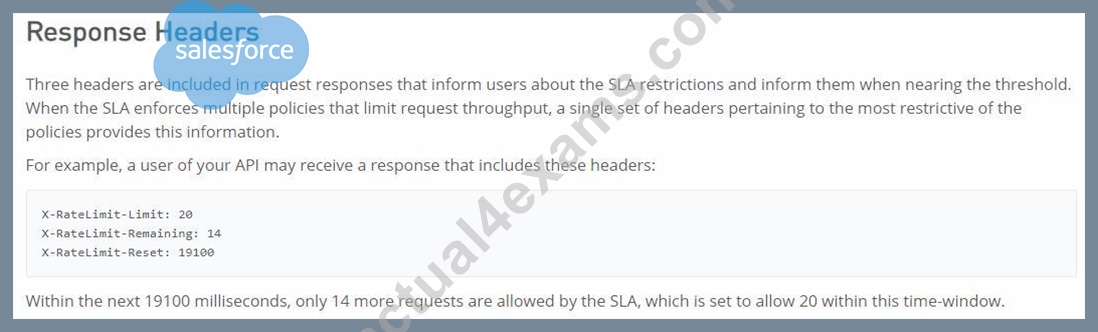
NEW QUESTION # 46
A retail company with thousands of stores has an API to receive data about purchases and insert it into a single database. Each individual store sends a batch of purchase data to the API about every 30 minutes. The API implementation uses a database bulk insert command to submit all the purchase data to a database using a custom JDBC driver provided by a data analytics solution provider. The API implementation is deployed to a single CloudHub worker. The JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker, and then the data is sent to an analytics engine using a proprietary protocol. This process usually takes less than a few minutes. Sometimes a request fails. In this case, the logs show a message from the JDBC driver indicating an out-of-file-space message. When the request is resubmitted, it is successful. What is the best way to try to resolve this throughput issue?
- A. Use a CloudHub autoscaling policy to increase the size of the CloudHub worker
- B. Increase the size of the CloudHub worker(s)
- C. se a CloudHub autoscaling policy to add CloudHub workers
- D. Increase the number of CloudHub workers
Answer: D
Explanation:
Correct Answer : Increase the size of the CloudHub worker(s)
*****************************************
The key details that we can take out from the given scenario are:
>> API implementation uses a database bulk insert command to submit all the purchase data to a database
>> JDBC driver processes the data into a set of several temporary disk files on the CloudHub worker
>> Sometimes a request fails and the logs show a message indicating an out-of-file-space message Based on above details:
>> Both auto-scaling options does NOT help because we cannot set auto-scaling rules based on error messages. Auto-scaling rules are kicked-off based on CPU/Memory usages and not due to some given error or disk space issues.
>> Increasing the number of CloudHub workers also does NOT help here because the reason for the failure is not due to performance aspects w.r.t CPU or Memory. It is due to disk-space.
>> Moreover, the API is doing bulk insert to submit the received batch data. Which means, all data is handled by ONE worker only at a time. So, the disk space issue should be tackled on "per worker" basis. Having multiple workers does not help as the batch may still fail on any worker when disk is out of space on that particular worker.
Therefore, the right way to deal this issue and resolve this is to increase the vCore size of the worker so that a new worker with more disk space will be provisioned.
NEW QUESTION # 47
Refer to the exhibit.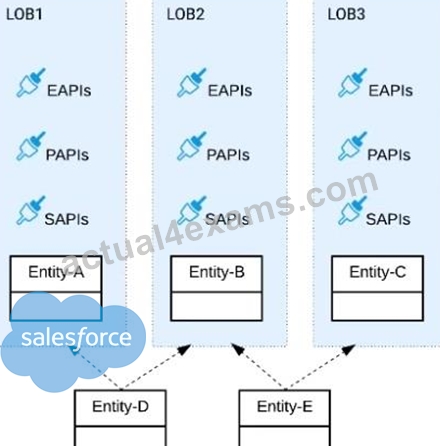
Three business processes need to be implemented, and the implementations need to communicate with several different SaaS applications.
These processes are owned by separate (siloed) LOBs and are mainly independent of each other, but do share a few business entities. Each LOB has one development team and their own budget In this organizational context, what is the most effective approach to choose the API data models for the APIs that will implement these business processes with minimal redundancy of the data models?
A) Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities
B) Build distinct data models for each API to follow established micro-services and Agile API-centric practices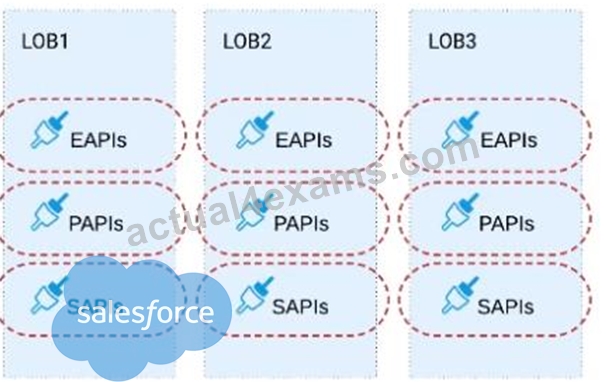
C) Build all API data models using XML schema to drive consistency and reuse across the organization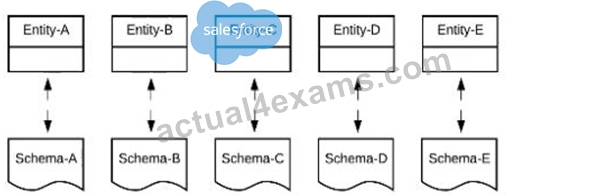
D) Build one centralized Canonical Data Model (Enterprise Data Model) that unifies all the data types from all three business processes, ensuring the data model is consistent and non-redundant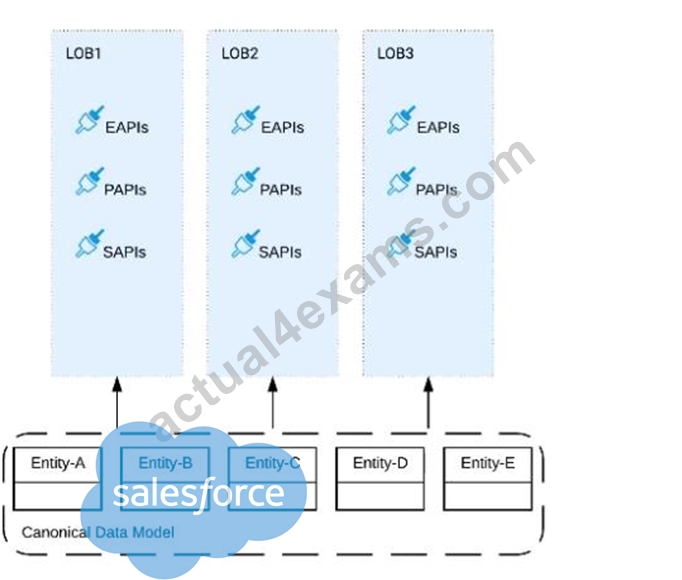
- A. Option D
- B. Option B
- C. Option A
- D. Option C
Answer: C
Explanation:
Correct Answer : Build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.
*****************************************
>> The options w.r.t building API data models using XML schema/ Agile API-centric practices are irrelevant to the scenario given in the question. So these two are INVALID.
>> Building EDM (Enterprise Data Model) is not feasible or right fit for this scenario as the teams and LOBs work in silo and they all have different initiatives, budget etc.. Building EDM needs intensive coordination among all the team which evidently seems not possible in this scenario.
So, the right fit for this scenario is to build several Bounded Context Data Models that align with coherent parts of the business processes and the definitions of associated business entities.
NEW QUESTION # 48
Refer to the exhibit.
What is the best way to decompose one end-to-end business process into a collaboration of Experience, Process, and System APIs?
A) Handle customizations for the end-user application at the Process API level rather than the Experience API level B) Allow System APIs to return data that is NOT currently required by the identified Process or Experience APIs C) Always use a tiered approach by creating exactly one API for each of the 3 layers (Experience, Process and System APIs) D) Use a Process API to orchestrate calls to multiple System APIs, but NOT to other Process APIs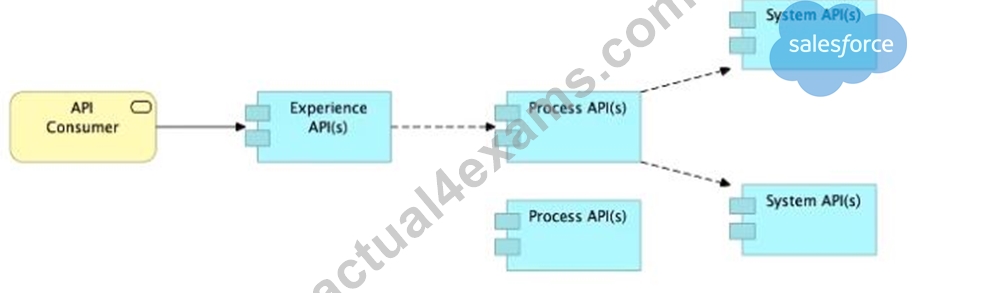
- A. Option A
- B. Option D
- C. Option B
- D. Option C
Answer: C
Explanation:
Correct Answe r: Allow System APIs to return data that is NOT currently required by the identified Process or Experience APIs.
*****************************************
>> All customizations for the end-user application should be handled in "Experience API" only. Not in Process API
>> We should use tiered approach but NOT always by creating exactly one API for each of the 3 layers. Experience APIs might be one but Process APIs and System APIs are often more than one. System APIs for sure will be more than one all the time as they are the smallest modular APIs built in front of end systems.
>> Process APIs can call System APIs as well as other Process APIs. There is no such anti-design pattern in API-Led connectivity saying Process APIs should not call other Process APIs.
So, the right answer in the given set of options that makes sense as per API-Led connectivity principles is to allow System APIs to return data that is NOT currently required by the identified Process or Experience APIs. This way, some future Process APIs can make use of that data from System APIs and we need NOT touch the System layer APIs again and again.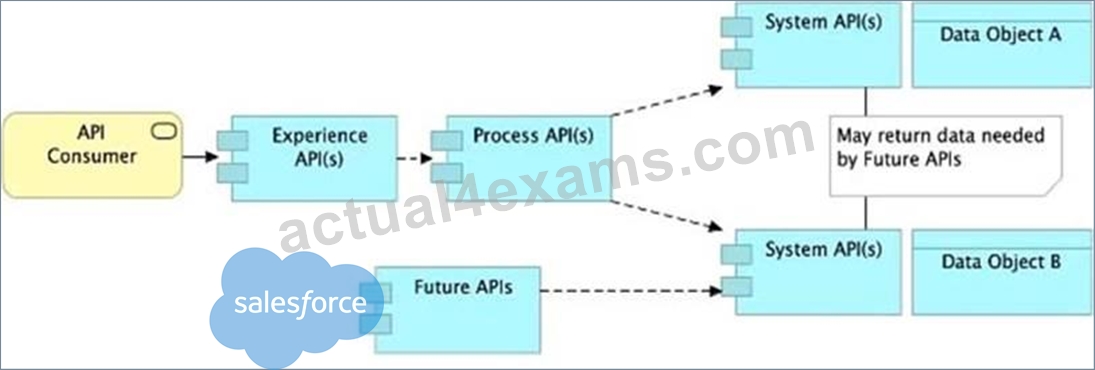
NEW QUESTION # 49
A circuit breaker strategy is planned in order to meet the goal of improved response time and demand on a downstream API.
* Circuit Open: More than 10 errors per minute for three minutes
* Circuit Half-Open: One error per minute
* Circuit Closed: Less than one error per minute for five minutes
Out of several proposals from the engineering team, which option will meet this goal?
- A. Create Anypoint Monitoring alerts for Circuit Open/Closed configurations, and then implement a retry strategy for Circuit Half-Open configuration
- B. Add the Circuit Breaker policy to the API instance, and configure the required settings
- C. Create a custom policy that implements the circuit breaker and includes policy template expressions for the required settings
- D. Implement the strategy in a Mule application, and provide the settings in the YAML configuration
Answer: B
Explanation:
Understanding Circuit Breaker Policy:
A circuit breaker is a design pattern used to detect failures and prevent an application from continually trying to execute a failing operation. In this case, it will help improve response time and reduce demand on the downstream API.
The specified configuration includes conditions for opening, half-opening, and closing the circuit based on error rates over time:
Circuit Open: Triggered if there are more than 10 errors per minute for three consecutive minutes.
Circuit Half-Open: The circuit transitions to half-open if there is one error per minute.
Circuit Closed: The circuit closes if the error rate is less than one error per minute for five minutes.
Evaluating the Options:
Option A: Creating a custom policy with template expressions could work, but it would require custom development. Since the Anypoint Platform already has a Circuit Breaker policy available, this would be a less efficient and more complex solution.
Option B: Anypoint Monitoring alerts can be used for monitoring the API, but they do not provide circuit-breaking functionality. Additionally, implementing a retry strategy for the half-open state is not sufficient to achieve the required circuit breaker behavior.
Option C (Correct Answer): Adding the Circuit Breaker policy to the API instance on Anypoint Platform allows you to set up circuit-breaking conditions directly. This approach uses the built-in Circuit Breaker policy, where you can configure parameters such as error thresholds and time intervals to match the requirements. This solution is efficient, reliable, and leverages Anypoint's out-of-the-box capabilities.
Option D: Implementing the strategy within a Mule application with a YAML configuration could be complex and less manageable. Additionally, it does not leverage Anypoint Platform's built-in Circuit Breaker policy, which is more suited to this scenario.
Conclusion:
Option C is the correct choice, as it leverages Anypoint Platform's Circuit Breaker policy. This solution allows for configuring thresholds and time intervals as specified, improving response time and reducing demand on the downstream API while utilizing Anypoint's managed policy feature.
Refer to MuleSoft's documentation on implementing the Circuit Breaker policy in API Manager for detailed configuration guidance.
NEW QUESTION # 50
What is true about where an API policy is defined in Anypoint Platform and how it is then applied to API instances?
- A. The API policy Is defined In Runtime Manager as part of the API deployment to a Mule runtime, and then ONLY applied to the specific API Instance
- B. The API policy Is defined In API Manager for a specific API Instance, and then ONLY applied to the specific API instance
- C. The API policy is defined in API Manager, and then applied to ALL API instances in the specified environment
- D. The API policy Is defined in API Manager and then automatically applied to ALL API instances
Answer: B
Explanation:
Correct Answer : The API policy is defined in API Manager for a specific API instance, and then ONLY applied to the specific API instance.
*****************************************
>> Once our API specifications are ready and published to Exchange, we need to visit API Manager and register an API instance for each API.
>> API Manager is the place where management of API aspects takes place like addressing NFRs by enforcing policies on them.
>> We can create multiple instances for a same API and manage them differently for different purposes.
>> One instance can have a set of API policies applied and another instance of same API can have different set of policies applied for some other purpose.
>> These APIs and their instances are defined PER environment basis. So, one need to manage them seperately in each environment.
>> We can ensure that same configuration of API instances (SLAs, Policies etc..) gets promoted when promoting to higher environments using platform feature. But this is optional only. Still one can change them per environment basis if they have to.
>> Runtime Manager is the place to manage API Implementations and their Mule Runtimes but NOT APIs itself. Though API policies gets executed in Mule Runtimes, We CANNOT enforce API policies in Runtime Manager. We would need to do that via API Manager only for a cherry picked instance in an environment.
So, based on these facts, right statement in the given choices is - "The API policy is defined in API Manager for a specific API instance, and then ONLY applied to the specific API instance".
NEW QUESTION # 51
......
Verified MuleSoft-Platform-Architect-I dumps Q&As - 100% Pass from Actual4Exams: https://www.actual4exams.com/MuleSoft-Platform-Architect-I-valid-dump.html
Pass MuleSoft-Platform-Architect-I Exam in First Attempt Guaranteed 2025 Dumps: https://drive.google.com/open?id=1gD_e58lale56hSTGQ947es53FEufKtuC